Following the last blog post, I would now document in more detail how we fixed the visual jank in the Android phones using WPE, it clearly shows testing an embedded engine in multiple devices is really valuable.
Originally, the Pixel 7 looked broken: a horizontal bar of stale content between tile rows, black corners appearing around spinners and rounded elements, and images that sometimes came up as solid rectangles of garbage. We tested multiple options to analyze the problem: it was not a tearing problem, the frames were correctly isolated, it was the frames rendering being wrong, which is much more complex to look into and much harder to profile.
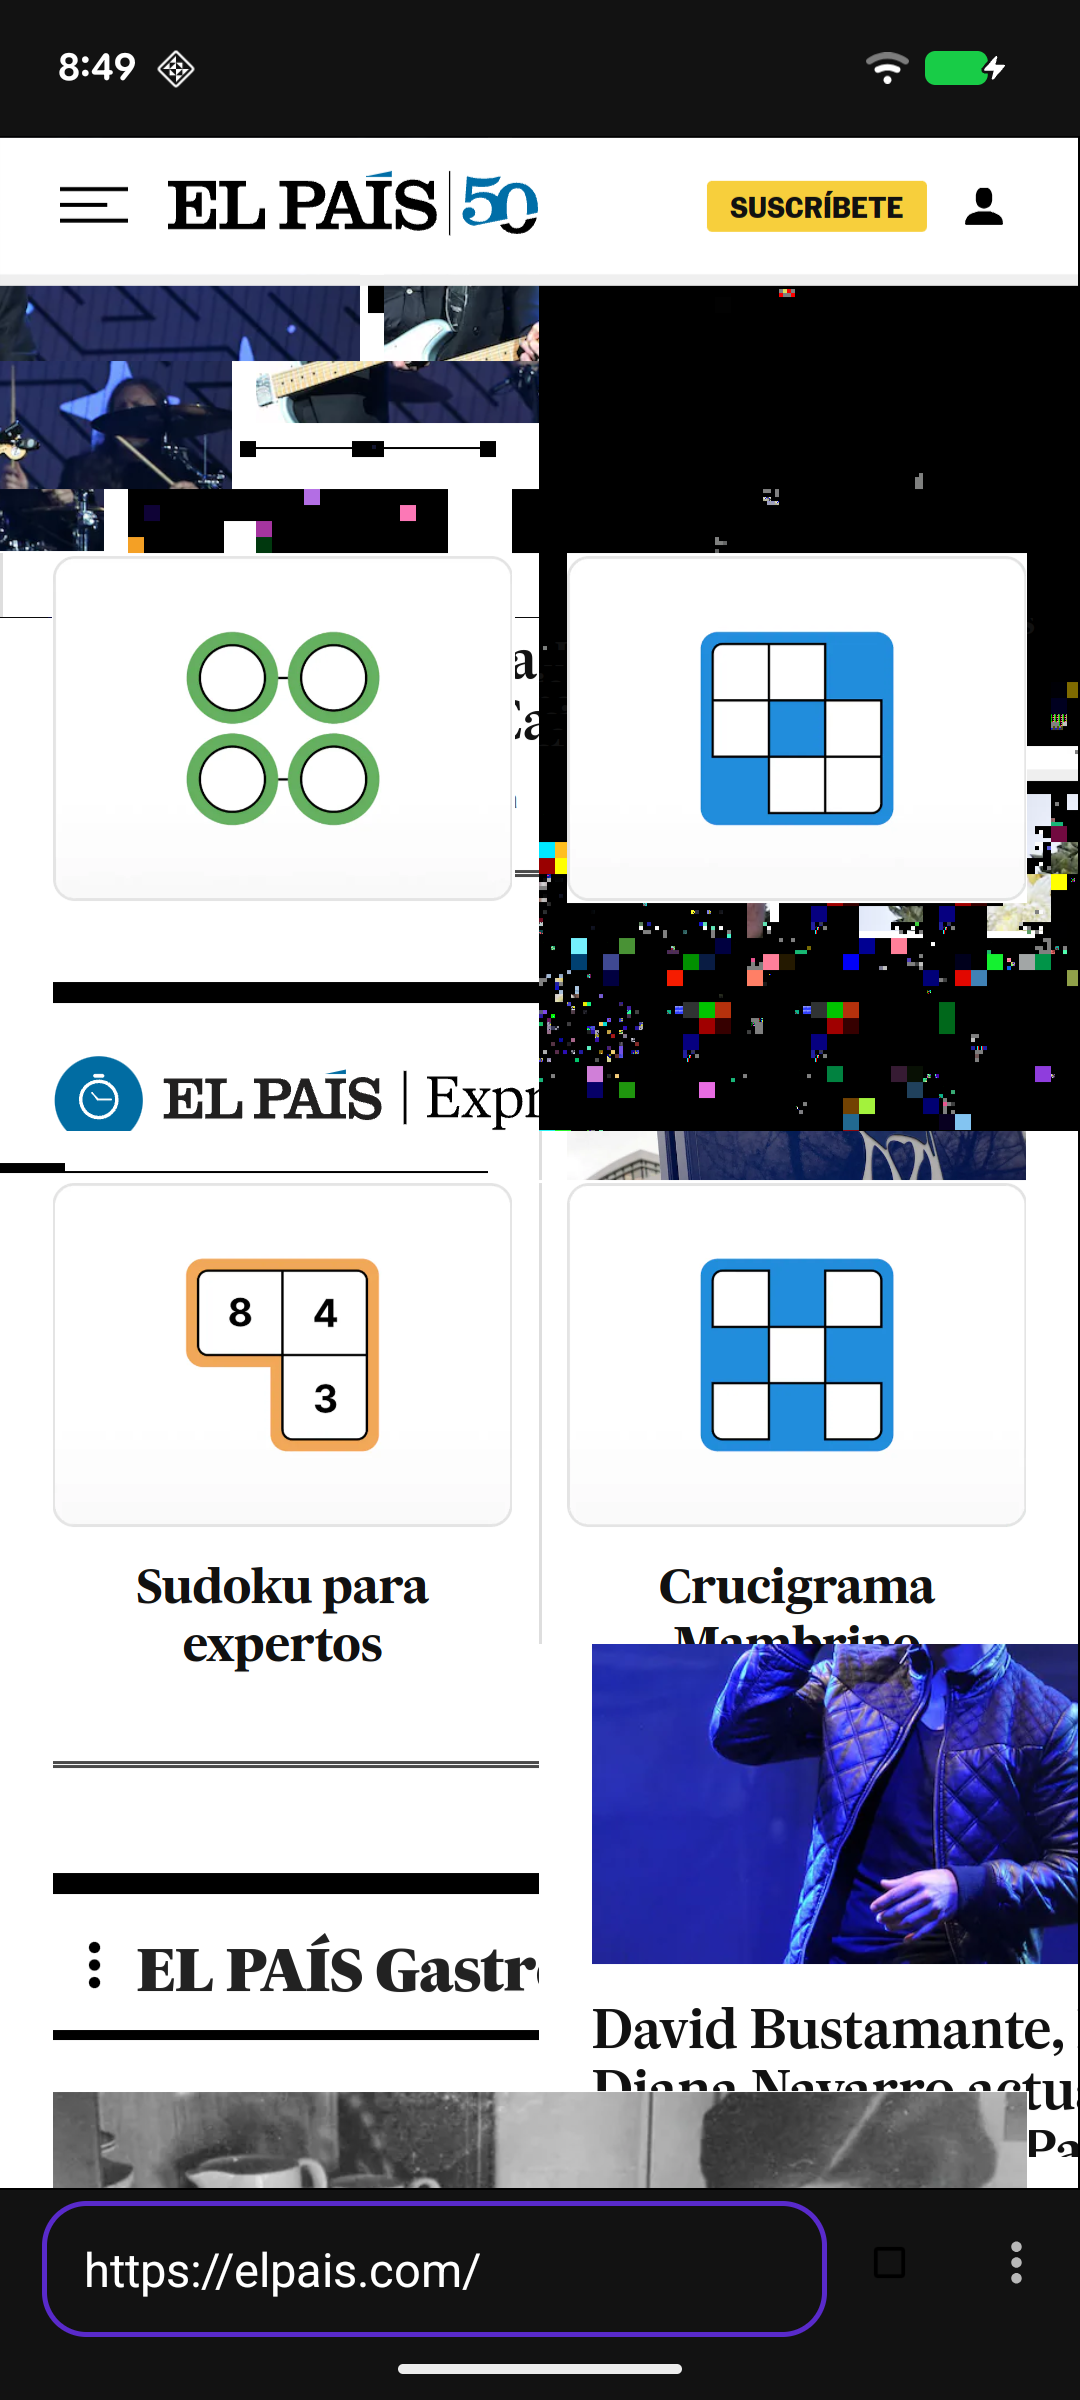
What eventually gave us the answer was testing different rendering configurations. Skia can rasterize on the CPU or on the GPU, we support both in WPE, and in both cases it can use a pool of worker threads, so when we ran some tests we verified:
- CPU with workers worked well, no jank.
- GPU on the main thread with no workers at all worked well, no jank.
- GPU with workers was broken: jank, every time.
So neither GPU rasterization nor parallelism was the problem on its own, it was the combination was causing the visual artifacts. The reason was that each painting worker has its own GrDirectContext, with its own GL context, sharing the underlying EGL display and textures with the context the compositor uses to put the frame together. That kind of sharing depends on the driver getting context synchronization right, and on Mali ((the Android driver for the Pixel 7 phone) it does not. We confirmed it by writting a small standalone reproducer outside WebKit.
The fix for all of that, which is Carlos’ WebKit PR #65286, uses a Skia feature that exists precisely for this kind of problem: deferred display lists. The feature comes from the idea of recording raster work in one place and executing it in the GPU process. In WPE we are currently still using a compositor thread with a GPU context, but the idea is the same. The approach is that you describe the destination surface up front, as a GrSurfaceCharacterization holding the surface properties, and you build a GrDeferredDisplayListRecorder from that description. The canvas you get from the recorder accepts and validates all the usual drawing, but does not send any GL commands at all, and at the end detach() gives you a GrDeferredDisplayList. The worker thread does all the expensive CPU side of painting (building the draw operations, resolving paints and geometry) with no GPU context required. Then the compositor thread, in SkiaBackingStore::Tile::update, creates or reuses an SkSurface compatible with the deferred operations object and calls skgpu::ganesh::DrawDDL with it. The compositor’s context is the only thing that ever renders tile content with the GPU context.
It is also very interesting how this is implemented. A thread with no GPU context can not sample a texture, so any image that already lives on the GPU (including the glyph and image atlases) can not be referenced directly while recording. Instead, they are turned into promise images. This is what makes atlas access safe from several recording threads at once. It is also the reason why, the first time we tested, every image was rendered as a black rectangle, which turned out to be an unrelated Android problem with the format used to upload those atlas textures, and cost us a couple of days wondering why the fix did not work.
Once it was activated, the Pixel 7 jank was gone, the bars, the black corners and the garbage in general. Also, parallel painting is still parallel, only the submission is serialized. There was a price, though: moving all the real rasterization to the compositor thread puts it in the same queue as frame presentation, and the first version felt slower. The cause was a fresh render target being allocated for every tile update, so adding a cache to recycle the backing buffer solved the problem.
Nowadays we are using DDL and the skia compositor by default, we plan to remove TextureMapper support, and the Skia compositor is what we provide in main.
The last part of the story is a warning note about benchmarks. When we ran a proper A/B testing with MotionMark, the overall score said deferred display lists were 7% slower, and that number was something we needed to understand: the whole difference came from a single subtest, Suits, which scored 76 against 19. The option without DDL was rendering incorrectly in Mali, so the benchmark in the end was rewarding broken frames in Android. The rendering was just find in Linux drivers where we tested it, so the decision took the whole situation into account. We did not want to add more rendering options (that usually means more complex maintenance), and the regression was measured against an architecture we knew was not completely safe.
Next time I could talk about how we are currently planning to recover that performance that is going to show pretty soon in the benchmarks, and it has taken some time because it requires patching Skia.